Showing posts with label scaling theory. Show all posts

Sunday, December 6, 2020

42. A study of fractal self-similarity and scaling for the De Bilt temperature data

In Post 9 (Fooled by randomness) I looked at the possibility of fractal behaviour occurring in the temperature records of individual stations and regions. In particular, I was interested to see if those records exhibited any form of self-similarity, and whether that self-similarity could account for the magnitude of fluctuations seen in the long term temperature records.

My initial analysis was performed on data from New Zealand and it seemed to suggest that fractal behaviour may be present. This behaviour is quantified by the fractal dimension which, in the case of temperature data, defines how the amplitude of the temperature fluctuations changes with the time interval those readings represent. Most of the data I look at on this blog consists of monthly average temperatures. For these readings the data typically has a spread of up to ±5 °C, while the standard deviation of the monthly fluctuations is usually between 1 °C and 2 °C. But what would the same temperature records look like if one considered the 12-month averages? Or the 10-year averages? 

Well, as I explained previously in Post 9, if the fluctuations in the temperature data conformed to a white noise spectrum, the power spectrum would be expected to be independent of frequency for all frequencies below the fundamental or cutoff frequency (see Eq. 9.1). The consequence of this is that smoothing the data with a sliding window, or moving average, of width N (where N is the number of months in the new average) should reduce the cutoff frequency by a factor of N, and thus reduce the signal power below the cutoff by a factor of N. That in turn should reduce the amplitude of the random noise fluctuations by a factor of √N. So, smoothing the monthly average data with a 24 month moving average should reduce the amplitude of the fluctuations by a factor of √24, or about a factor of five. Except that this does not happen.

As I have demonstrated in numerous previous posts, the noise amplitude in the monthly temperature data decreases much more slowly than expected as the width of the sliding window in the smoothing algorithm is increased. In fact it appears to decrease as N -p. where p tends to be in the range 0.20 < p < 0.35, but is generally concentrated around p = 0.25. This was shown in Post 9 for New Zealand data, in Post 17 for individual sites in Australia, and in Posts 18-21 for various Australian states. In most cases the same behaviour was seen. The only two exceptions I have found so far were for data from the South Pole (Amundsen-Scott), and also for the trend for South Australia (see Post 21) but only if the parabolic long term trend was removed. In both cases the data behaved like classical white noise with p = 0.5.

Why is this behaviour important? Well, for three reasons. Firstly, if there is a definite trend, it would allow us to estimate the amplitude of natural temperature fluctuations over timescales that are much longer than we have data for. Secondly, it could allow us to differentiate between natural and anthropogenic sources of climate change. And finally, it may shed light on possible natural mechanisms that may underpin long term climate change rather than assuming that everything is a consequence of carbon dioxide emissions, or that every current change in climate behaviour has a cause that is local, either spatially or temporally.

So why I am revisiting this now? Well, because in my last post I presented some data from a station at De Bilt (Berkeley Earth ID: 175554) in the Netherlands that is one of the longest continuous sets of temperature data that exists. What also set this data apart, though, was the fact that there was complex structure to the data that was much greater in amplitude than the continuous upward trend expected from global warming. Moreover, the underlying continuous upward trend could also be easily removed so that the remaining data could be studied, just as I removed the parabolic background from the South Australia data in Post 21. The question is, would I see the same result as for South Australia? Namely, that the remaining temperature fluctuations behaved like white noise. Well, the answer is no.


Fig. 42.1: The monthly temperature anomalies for De Bilt since 1706 with the linear trend of +0.29 ± 0.04 °C per century removed (blue curve). The standard deviation is 1.855 °C (for N = 1). The yellow curve is the 12-month moving average of the blue data (N = 12) and has a standard deviation of 0.810 °C.


The data in Fig. 42.1 above shows the same monthly temperature anomaly data that was presented in Fig. 41.1 of the previous post, except with the long-term upward trend of 0.23 °C per century removed. The yellow curve is the 12-month moving average of the blue data which clearly has a much lower noise amplitude, and therefore a lower standard deviation of 0.81 °C compared to 1.85 °C for the monthly data. In both cases the standard deviation was measured for data over the same 275 year period (or 3300 months) from 1731-2005.


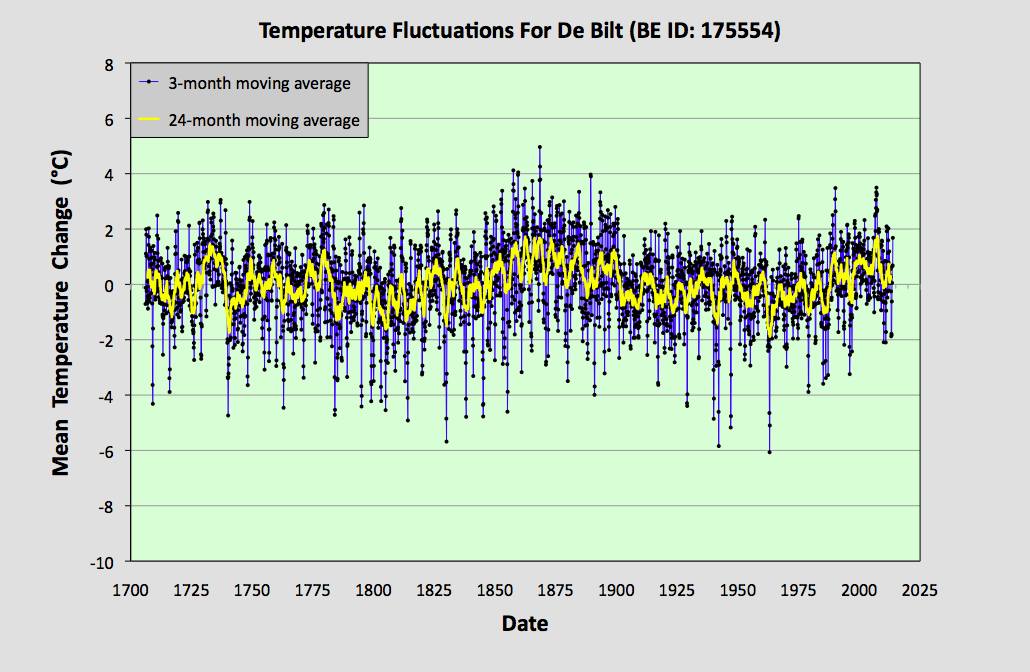
Fig. 42.2: The 3-month (N = 3) moving average (blue curve) of the monthly data in Fig. 42.1 above. The standard deviation of this data is 1.326 °C. The yellow curve is the 24-month moving average (N = 24) of the same data in Fig. 42.1 and has a standard deviation of 0.664 °C.


The data in Fig. 42.2 above shows the same monthly temperature anomaly data as shown in Fig. 42.1, but after smoothing with a 3-month moving average (blue curve) and alternatively a 24-month moving average (yellow curve). As a result of the smoothing, the standard deviation reduces to 1.326 °C for the 3-month window (N = 3) and 0.644 °C for the 24-month sliding window (N = 24).


Fig. 42.3: The 6-month (N = 6) moving average (blue curve) of the monthly data in Fig. 42.1 above. The standard deviation of this data is 1.046 °C. The yellow curve is the 5-year moving average (N = 60) of the same data in Fig. 42.1 and has a standard deviation of 0.536 °C.


Next, if we smooth the original monthly temperature anomaly data in Fig. 42.1 with 6-month and 5-year moving averages or sliding windows we get the data shown in Fig. 42.3 above. Now, after smoothing with a 6-month moving average (blue curve) the standard deviation has reduced to 1.046 °C (and N = 6), while that for the 5-year moving average (yellow curve) is now 0.536 °C (and N = 60).


Fig. 42.4: The 9-month (N = 9) moving average (blue curve) of the monthly data in Fig. 42.1 above. The standard deviation of this data is 0.894 °C. The yellow curve is the 10-year moving average (N= 120) of the same data in Fig. 42.1 and has a standard deviation of 0.462 °C.


Finally, if we smooth the original monthly temperature anomaly data in Fig. 42.1 with 9-month and 5-year moving averages or sliding window we get the data shown in Fig. 42.4 above. Now, after smoothing with a 9-month moving average (blue curve) the standard deviation has reduced to 0.894 °C (and N = 9) while that for the 10-year moving average (yellow curve) is now 0.462 °C (and N = 120).

All the standard deviations (σ) for the different sets of smoothed data are summarized in the table below.


Table 42.1
N σ ln(N) ln(σ)
1
1.855
0.000
0.618
3
 1.326  1.099  0.282
 6  1.046  1.792  0.045
 9  0.894  2.197  -0.112
 12  0.810  2.485  -0.211
 24  0.664  3.178  -0.409
 60  0.536  4.094  -0.624
 120  0.462  4.787  -0.772


If we now combine these results into a single plot we get the graph shown in Fig. 42.5 below. The gradient of this log-log plot is the exponent of N -p in the power law we expect to see for the decrease in the noise amplitude as we increase the smoothing interval N. Once again we see that the value for the exponent p is well below the 0.5 expected for white noise. In fact p = +0.31 ± 0.01, indicating that the fractal dimension is 0.31. In addition, the quality of the fit (as indicated by the R2 value) is very high.


Fig. 42.5:  Plot of the standard deviation of the smoothed anomaly data against the smoothing interval N for temperature data from De Bilt. The best fit line is fitted to all the data except that from the 10-year moving average (as indicated by the length of the red line). The gradient of the best fit line is -0.31 ± 0.01 and R2 = 0.9943.


Conclusions

  1. The quality and linearity of the best fit in Fig. 42.5 indicates that there is a high degree of self-similarity in the data. This in turn also suggests that all the significant features seen in the original data (such as the large broad peaks at 1725 and 1860) are natural and not the result of external or artificial biases. If such artificial biases were present, and were significant in magnitude, they would probably manifest themselves as significant deviations of the data in Fig. 42.5 from a linear trend.
  2. From the gradient of the trend line in Fig. 42.5 we can estimate the standard deviation of temperature data for the case N = 1200 as being 0.20 °C. In other words, the fluctuations in the 100-year average will typically be of the order of ±0.2 °C. This in turn suggests that changes in the mean temperature from century to century of more than 0.5 °C are likely to be very common.


Sunday, August 2, 2020

28. No AGW in Australia? A summary of trends.


Fig. 28: 10-year average temperature trends for Australia based on actual raw data (blue curve) and Berkeley Earth adjusted data (orange curve). The gradient of the best fit to the actual raw data (red line) is +0.18 ± 0.02 °C per century. The temperature change is relative to the 1961-1990 average.


My previous ten posts have examined the temperature records of Australia, state by state, and then also examined the combined result. The final results, based on my analytical methods, are summarized as follows.

1) The mean temperatures in Australia since 2000 are at most 0.2 °C higher, and probably less than 0.1 °C higher than those seen in the latter part of the 19th century (see Fig. 26.1).

2) The average temperature in Australia over the course of the entire 20th century was 0.063 °C lower than the equivalent value for the last 50 years of the 19th century.

3) The average temperature in Australia from 1950-1999 was only 0.1 °C higher than the average for the last 50 years of the 19th century.

4) The fluctuations in the temperature of Australia show a scaling behaviour with a fractal dimension of 0.26 (see Fig. 27.2). This suggests that most of the features in the smoothed data, or data averaged over long timescales, are just low frequency noise. Similar effects are seen in the data for most states, and also in the data for New Zealand (see Post 9).

5) The scaling behaviour of the anomalies implies that the 100-year average temperature for Australia would still have fluctuations with a standard deviation of more than 0.10 °C. This is more than the temperature difference observed between the values for the mean temperature of the latter half of the 19th century and that of the latter half of the 20th century. Thus, the temperature rise seen in the latter half of the 20th century is within the range that would be expected based on random chaotic fluctuations.

6) Only Western Australia and Queensland appear to have had noticeably higher temperatures after the year 2000 compared to the late 19th century. This is partly explained by the fact that both states have little or poor data before 1890.

7) The various adjustments made to the individual temperature records by climate groups like Berkeley Earth appear to have had a significant impact on the overall warming trend for Australia when compared with my more simplified (but in my view more justifiable) statistical methodology. This means that the statistical methods used to analyse the data, and their rationale, are of critical importance and need to be thoroughly tested, evaluated, and justified. The first step in doing this should always be to compare the results based on the adjustments with those obtained without the adjustments. That has always been the primary raison d'être of this blog.

8) The overall effect of adjustments made to the individual temperature records of Australia by Berkeley Earth, when compared to my results, has been to partially flatten the curve in Fig. 26.1 before 1900 and to increase the warming trend by up to 0.3 °C after 1900 (see Fig. 26.5). These adjustments are not neutral and completely change the shape of the curve.

9) The overall temperature trend for Australia looks more like a parabola or low frequency oscillation when the raw data is averaged according to my statistical procedure. The effect of the adjustments made to the data by Berkeley Earth is to make the temperature trend look more like a hockey stick (see Fig. 26.4).

Given the shape of the overall instrumental temperature record illustrated in Fig. 26.1, it is difficult to see how this could constitute unambiguous evidence for anthropogenic global warming (AGW). The best (or worst) that can be said about the data is that it is ambiguous. However, it also represents an alternative self-consistent narrative that raises profound questions about the current climate warming zeitgeist.

If my averaging methods for the anomaly data were simplistic to the point of being erroneous, the result would be a mean temperature trend in Fig. 26.1 that was totally uncorrelated with the majority of the individual records from which it was formed. Yet there is no evidence that this is the case. In fact the majority of long temperature records for Australia look very similar to the mean trend shown in Fig. 26.1.

But it is the scaling behaviour that is the killer application. If this phenomenon is real and ubiquitous, then it implies that (almost) everything that is seen in the temperature record is just chaotic noise. The only exception might be the urban heating I described here, and which is clearly important in those parts of the world that have high levels of industry and high population densities. But that is unlikely to be important in most of the Southern Hemisphere.

Wednesday, July 15, 2020

21. South Australia - temperature trends PARABOLIC

South Australia has a population density of 1.7 people per square kilometre. Only Western Australia and Northern Territory have lower densities. Yet South Australia still has 57 weather stations with more than 480 months of data. Of these 7 are long stations with more than 1200 months of data, and an additional 11 have between 900 and 1200 months of data. Its data is, therefore, comparable in terms of length and quality with that found in Victoria, but is still not as good as that for New South Wales.


i) Weather station distribution

The location of the 57 long and medium stations are shown in Fig. 21.1 below. Most of the stations are situated towards the south of the state, with only 10 medium stations located above the 32nd parallel (which bisects the state). This means that the stations in South Australia are not evenly distributed across the state, nor are they fully representative of the overall climate of the state.


Fig. 21.1: The locations of long stations (large squares) and medium stations (small diamonds) in South Australia. Those stations with a high warming trend since 1841 are marked in red.


The station locations shown in Fig. 21.1 differentiate between those stations that have warming trends and those where the trend is negative or stable. I have defined a warming trend to be one where the slope of the best fit to the temperature trend is positive and more than twice the error in the gradient (i.e. 95% confidence). Based on the distribution of stations in Fig. 21.1, it appears that most of the warming in South Australia is found in the west of the state. However, it needs to be recognized that most of those stations are shorter length stations with more recent data. As the data in Fig. 20.2 below indicates, the overall trend in South Australia is a warming one in the latter half of the 20th century. That coincides with the time-frame of operation of most of the medium and short stations.


ii) The trend in mean temperature


Fig. 21.2: Temperature trend for long stations in South Australia since 1857. The best fit linear trend line (in red) is for the period 1857-2012 and has a gradient of -0.087 ± 0.055 °C/century.


Adding the temperature anomalies from all stations in South Australia with more than 480 months of data yields the trend shown in Fig. 21.2 above. In this case the monthly reference temperatures (MRTs) for each station were calculated for the period 1961-1990. The MRT was then subtracted from the raw data to generate the temperature anomaly.

The trend in overall temperature since 1870 indicated in Fig. 21.2 is similar to that seen for both New South Wales and Victoria. There is evidence of a decline in temperatures from 1860 to 1940 followed by a slow rise. In this case the overall temperature trend from 1857 to 2012 (as indicated by the red line) is -0.087 ± 0.055 °C per century. In other words, overall South Australia has experienced a very low or moderate cooling since 1860. However, the real picture is of two distinct trends; a large cooling of over 1 °C for the period up to 1940, and a similar warming for the period since. This suggests that far from the climate being stable, it is continuously changing, and the warming we see in much of Australia since 1940 is not exceptional. Cooling phases of similar magnitudes have occurred previously.


iii) The Berkeley Earth (BE) mean temperature trend


Fig. 21.3: Temperature trend for long stations in South Australia since 1840 derived using the Berkeley Earth adjusted data. The best fit linear trend line (in red) is for the period 1941-2010 and has a gradient of +1.66 ± 0.08 °C/century.


If we repeat the temperature averaging process for the Berkeley Earth adjusted data we get the trend shown above in Fig. 21.3. This also shows an initial slight downward trend before 1940, but one that only amounts to about 0.3 °C. After 1940 there is a strong positive trend of +1.62 ± 0.07 °C/century that raises the overall temperature by over 1.1 °C before 2010. The trend in Fig. 21.3 is qualitatively similar to the plot shown on the Berkeley Earth site (see Fig. 21.4 below), and also resembles both the IPCC "hockey stick" and the instrumental temperature record since 1850. Again, this level of agreement between the data in Fig. 21.3 and Fig. 21.4 effectively supports our averaging process as it implicitly refutes the need to introduce station weighting coefficients.


Fig. 21.4: Temperature trend for South Australia since 1840 according to Berkeley Earth.


The data presented in Fig. 21.3 and Fig. 21.4 is the 12-month moving average, but the same general trends in the data are also seen in the monthly averages of the Berkeley adjusted data (see Fig. 21.5 below). The best fit to this data over the period 1841-2010 is a modest 0.429 ± 0.052 °C per century, but this still equates to an overall temperature rise of more than 0.8 °C since 1841. That is indeed similar to the temperature rise seen after 1941 for the raw data in Fig. 21.2, but the overall picture it presents is completely different. The reason for the difference becomes apparent if you look at how and where the differences arise.


Fig. 21.5: Temperature trend for all long and medium stations in South Australia since 1857 based on Berkeley Earth adjusted monthly data. The best fit linear trend line (in red) is for the period 1857-2012 and has a gradient of +0.429 ± 0.052 °C/century.


iv) Comparison of unadjusted and BE adjusted temperature data

The difference between the data in Fig. 21.5 and that in Fig. 21.2 is almost entirely due to the adjustments made to the data by Berkeley Earth (BE). These adjustments are shown in Fig. 21.6 below.

The adjustments made to the data by Berkeley Earth appear to be of two main types. Generally, the most significant tend to be the breakpoint adjustments that I have discussed previously. These are supposed to compensate for measurement errors in the original data. However, there appears to be a second adjustment that is introduced when the MRTs are calculated. As I wrote previously, the source of this is unclear, but I suspect it arises from a homogenization process being used to determine the MRT for each dataset, rather than the MRT being determined purely by averaging the data from within that dataset as I have done for Fig. 21.2.


Fig. 21.6: The Berkeley Earth breakpoint adjustment (in yellow) for Tasmania since 1840 together with the difference between the Berkeley Earth adjusted anomaly and the raw anomaly (in blue). The best fit (red line) to the total adjustment (blue curve) is +0.30 ± 0.03 °C per century.


In the case of the South Australia data, the MRT adjustments, although large in amplitude, do not seem to have as great an impact on the trend as the breakpoint adjustments.  The sum total of the two adjustments is illustrated by the blue curve in Fig. 21.6 above. Together they add 0.30 ± 0.03 °C per century to the trend between 1911 and 2010 (see the red best fit line in Fig. 21.6). Of this, the breakpoint adjustments contribute 0.19 °C per century (see the yellow curve in Fig. 21.6). The net result is to lift the slope of the trend curve by 0.3 °C per century between 1911 and 2010. That amounts to a rise in the final temperature after 2010 of 0.3 °C as well. This, though, is only half the story.

What we can also see in Fig. 21.6 is that the total effect of all the adjustments is to introduce a negative cooling for the period 1857-1900 of up to 1 °C. The justification for this is presumably that the high temperatures before 1900 are inconsistent will the global trend. The problem is that they are all too consistent with the trends seen in the rest of Australia and in New Zealand.

As I pointed out in the last post, you do not need to eradicate the peaks and troughs in the temperature trend before 1900 (and nor should you) because these peaks and troughs are real, not erroneous artefacts that need to be expunged. And even if these peaks and troughs are not real, the appropriate way to deal with them is to use more data and see if they average out. In the case of Tasmania this was not possible because there was only one significant but imperfect temperature record for the period 1840-1900. In South Australia, however, we have at least four. And like the Tasmania data, it is consistent with data in NSW and Victoria over the same time-frame.

As I have outlined above, these adjustments that Berkeley Earth apply are not neutral. They significantly alter the temperature trend, and they do this because they do not just add to the positive trend post-1940 (thus enhancing the blade of the so-called hockey stick), they also help to erase the peaks in the anomaly data before 1990 (thereby smoothing the handle of the hockey stick). It is the combination and interaction of these two effects that so dramatically changes the temperature trend from the one I have calculated in Fig. 21.2 to the Berkeley Earth version in Fig. 21.5.


v) Noise and its scaling behaviour


Fig. 21.7: The standard deviation of the South Australia mean anomaly after smoothing with a moving average of size N. The gradient of the best fit line is -0.290 ± 0.015 and R2 = 0.9869.


Finally, if we look at the effect of data smoothing on the noise level, we again appear to see strong evidence of scaling behaviour (see Fig. 21.7 above). Once again the noise (as defined by the standard deviation) scales as N -a with the exponent a = 0.290 ± 0.015. This is similar to the scaling seen previously for NSW (a = 0.272 ± 0.005) and Victoria (a = 0.257 ± 0.015). However, here things are not quite so straight-forward.

The data in Fig. 21.7 shows evidence of a distinct curvature away from the linear regression best fit line. This suggests that the scaling may only be valid for low values of N and the log-log plot may not be truly linear. This appears to be confirmed by the plot in Fig. 21.8 below.


Fig. 21.8: The standard deviation of the South Australia mean anomaly after smoothing with a moving average of size N , but with a negative offset of 0.2 applied each time. The gradient of the best fit line is -0.465 ± 0.007 and R2 = 0.9988.


In Fig. 21.8 the standard deviation for each set of smoothed data is offset by a fixed amount (in this case 0.2). The reasoning here is that some of the standard deviation may not be from noise, but from an underlying linear trend for the data such as that seen in the upward slope of the Berkeley Earth data in Fig. 21.3 after 1940. Such a slope would itself have a standard deviation of ∆y/4√3 where ∆y is the change in vertical height up the slope.

The data in Fig. 21.2 effectively has two such slopes, a negative one before 1940 and a positive one after. Each slope will have the same standard deviation of 0.2 °C as ∆y = 1.4 °C (approximately) in each case. Thus if we subtract 0.2 from each standard deviation in Fig. 21.7 we get an approximate value for the standard deviation of the noise and not the slope. This data is plotted in Fig. 21.8 above.

What we find is that we still get a power law of the type N -a, but the index changes to a = 0.465 ± 0.007. More significantly, the residual between the data and the best fit reduces significantly from 11.4% of the standard deviation of y-values to 3.5%, thereby indicating how much the linear regression best fit has improved.


Fig. 21.9: The standard deviation of the South Australia mean anomaly, minus the parabolic best fit, after smoothing with a moving average of size N. The gradient of the best fit line is -0.465 ± 0.007 and R2 = 0.9988.


Alteratively, we could remove the underlying trend in Fig. 21.2 altogether. This trend is clearly parabolic to first order and can be approximated by the equation y = a(x-b)2 - c, where a = 0.00016, b = 1940, and c = 0.2. Subtracting this function from the mean anomaly data in Fig. 21.2 yields a dataset which has no underlying warming trend for the the entire timescale 1857-2013, but has the same monthly fluctuations as the data in Fig. 21.2. If the same scaling analysis is performed on this modified data as was undertaken in Fig. 21.7, the result is a different power law as shown in Fig. 21.9. This time we find that a = 0.456 ± 0.007. This is very close to the value of 0.5 we would expect for white noise. In addition the residual reduces even further to 3.4%.

So do we have white noise on a smoothly varying background (as demonstrated by Fig. 21.9) or do we have a quasi-fractal with a much lower power law? So far it is too early to tell. We do not have enough data. What is clear is that it is not only the South Australia data that exhibits this behaviour. It can also be seen (but was missed on first analysis) in Victoria (see Fig. 19.7) and Tasmania (see Fig. 20.8). In these two cases, however, the underlying trend was not parabolic or linear, particularly before 1900, so the modifications made in Fig. 21.8 and Fig. 21.9 above would not be applicable. In order to investigate this further, we probably need longer datasets. These will only be found in the Northern Hemisphere.


vi) Conclusions

1) The overall temperature trend for South Australia since 1857 shows no evidence of anthropogenic climate change.

2) Temperatures in the 1850s were probably greater than they are now.

3) Temperatures were much lower in the 1940s than they are now. 

4) The overall temperature trend for South Australia since 1860 is broadly similar to that seen for both New South Wales and Victoria.

5) Berkeley Earth breakpoint adjustments and other adjustments (possibly from homogenization) have once again significantly changed the form and shape of the long-term temperature trend (see Fig. 21.3 and Fig. 21.5 and Fig. 21.6).

6) The noise level in the regional average of monthly anomalies (see Fig. 21.3) is similar to the noise level in the individual records. The averaging process has little effect on the noise level.

7) The noise in the regional temperature average for South Australia may scale in a similar way to that seen for New South Wales except that the power law is N - 0.29, where N is the size of the sliding window in the moving average (see Fig. 21.7). Or it could be white noise on a parabolic (or sinusoidal) background signal (see Fig. 21.9).

Thursday, July 9, 2020

19. Victoria (Australia) - temperature trends PARABOLIC

The state of Victoria in Australia has 65 sets of weather station data that are longer than 480 months (the equivalent of 40 years), of which 15 are long stations with over 1200 months of data. While this is not as extensive a set of station data as is seen for New South Wales (NSW) and was discussed in the previous post, it is still more than was seen for New Zealand. In this post I will essentially repeat the analysis that was performed on the NSW data last time but with data from Victoria. The aim is to see if the trends seen in NSW and Victoria are just local, or whether they are indicative of a common trend across the whole of Australia.


i) Weather station distribution

The long stations in Victoria are fairly evenly distributed across the state, as illustrated in Fig. 19.1 below. So, in their totality, they are fully representative of the overall climate of the state.


Fig. 19.1: The locations of long stations (large squares) and medium stations (small diamonds) in Victoria. Those stations with a high warming trend since 1871 are marked in red.


The station locations shown in Fig. 19.1 also differentiate between those stations that have warming trends and those where the trend is negative or stable. I have defined a warming trend to be one where the slope of the best fit to the temperature trend is positive and more than twice the error in the gradient (i.e. 95% confidence). Based on the distribution of stations in Fig. 19.1, it appears that most of the warming in Victoria is found in and around Melbourne. A similar trait was seen in New South Wales around Sydney, suggesting that urban heating is a significant issue.


 Fig. 19.2: The amount of warming for long and medium stations in Victoria. The stations with definite warming trends are shown as red squares.


It can be seen in Fig. 19.2 that only 4 of the 15 long stations have a warming trend. For stations with more than 600 months of data only 15 of the 42 stations have a warming trend. For shorter length stations the warming is more pronounced, but these stations add little to the overall trend for the region because of their limited length.


ii) The trend in mean temperature


Fig. 19.3: Temperature trend for long and medium stations in Victoria since 1850. The best fit to the data has a gradient of -0.05 ± 0.08 °C per century.


Adding the temperature anomalies from all stations with more than 480 months of data yields the trend shown in Fig. 19.3 above. In this case the monthly reference temperatures (MRTs) were calculated for the period 1981-2010. This period is longer than1981-2000 period used for the New Zealand data so the MRT values are likely to be more stable. The period is also 20 years later than the 1961-1990 period favoured by most climate scientists. The 1981-2010 period was chosen because it allows most of the medium station data to be used. However, overall these changes make little difference to the final result.

The trend in Fig. 19.3 very similar to that for New South Wales shown in Fig. 18.3 previously. In this case the overall temperature trend from 1890 to 2007 (as indicated by the red line) is -0.05 ± 0.08 °C per century. In other words, there is no warming taking place.


iii) The Berkeley Earth (BE) mean temperature trend 


Fig. 19.4: Temperature trend for long and medium stations in Victoria since 1850 derived using the Berkeley Earth adjusted data. The best fit to the data has a gradient of +1.64 ± 0.08 °C per century.


However, if we repeat the averaging process for the temperature data, but use Berkeley Earth adjusted data, we get the trend shown above in Fig. 19.4. This also initially shows a slight downward trend, but only before 1940, after which there is a strong positive trend of +1.64 ± 0.08 °C/century that raises the overall temperature by over 1.1 °C before 2010. The trend in Fig. 19.4 is almost identical to the plot shown on the Berkeley Earth site (see Fig. 19.5 below), and also resembles both the IPCC "hockey stick" and the instrumental temperature record since 1850, at least qualitatively.


Fig. 19.5: Temperature trend for Victoria since 1840 according to Berkeley Earth.


The difference between the data in Fig. 18.5 (or Fig. 18.4) and that in Fig. 18.3 is almost entirely due to the adjustments made to the data by Berkeley Earth. These are shown in Fig. 18.6 below.


Fig. 19.6: The Berkeley Earth breakpoint adjustment for Victoria since 1840 together with the difference between the Berkeley Earth adjusted anomaly and the raw anomaly (in blue). The best fit (red line) to the difference data is +0.60 ± 0.02 °C per century. The yellow curve is the contribution to the difference from breakpoint adjustments


The adjustments made to the data by Berkeley Earth appear to be of two main types. The most significant are the breakpoint adjustments that I have discussed previously. These are supposed to compensate for measurement errors in the original data. However, there appears to be a second adjustment that is introduced when the MRTs are calculated. The source of this is unclear, but I suspect it arises from a homogenization process being used to determine the MRT for each dataset, rather than just averaging the data from within that dataset as I have done. The homogenization process probably uses data from adjacent local stations to help refine the MRT. Whatever the source, it is clear from Fig. 19.6 that these adjustments are not neutral and they significantly alter the temperature trend.

What we can see in Fig. 19.6 is that the total effect of all the adjustments is to introduce a positive warming of +0.60 ± 0.02 °C/century for the period 1881-2010, of which +0.39 ± 0.02 °C/century is due to the breakpoint adjustments. This equates to a temperature rise of at least 0.78 °C being added to the original data between 1881 and 2010 by the Berkeley Earth data processing.


iv) Noise and scaling behaviour


Fig. 19.7: The change in standard deviation of the Victoria mean temperature anomaly after smoothing with a moving average of size N. The gradient of the best fit line is -0.257 ± 0.015 and R2 = 0.9842.


Finally, if we look at the effect of data smoothing on the noise level, we again see strong evidence of scaling behaviour (see Fig. 19.7 above). This time the noise (as defined by the standard deviation) again scales as N -a with the exponent a = 0.257 ± 0.015. Once again, this is very similar to the scaling seen for New South Wales previously where a = 0.272 ± 0.005, and implies a noise level (i.e. standard deviation) on 100-year averaged temperature data of at least 0.16 °C. This is similar to the value predicted for individual stations such as Newcastle Nobbys Signal Station (Berkeley Earth ID - 152044) that was studied in Post 17. That study indicated that fluctuations in the 100-year temperature average of over 0.5 °C could be commonplace over 2000 year time periods (see Fig. 17.8).


v) Conclusions

1) Based on the original station data, there is no evidence of any rise in overall temperatures in Victoria since 1881 (see Fig. 19.3).

2) The overall temperature trend for Victoria since 1850 is very similar to that seen for New South Wales.

3) The long-term temperature trend for Victoria exhibits fluctuations of more than ±2 °C over timescales of more than 100 years (see Fig. 19.3). Even the 5-year moving average has fluctuations of at least ±0.5 °C, and maybe as much as ±1 °C. This adds to previous evidence that suggests that what we are probably seeing in these temperature trends is primarily low frequency noise or random fluctuations.

4) Breakpoint adjustments and other adjustments (possibly from homogenization) can completely change the form and shape of the long-term temperature trend (see Fig. 19.4). They are not neutral.

5) Breakpoint adjustments added at least 0.5 °C to the long-term temperature trend for Victoria (see Fig. 19.6). Other adjustments increased this to nearly 0.8 °C.

6) The noise in the regional temperature average for Victoria scales in a similar way to that seen for New South Wales except that the power law is N -0.26, where N is the size of the sliding window in the moving average (see Fig. 19.7).

7) As the standard deviation for the 60-month smoothed temperature anomalies is 0.36 °C, this means that there is still a 50% probability of a temperature rise of more than 0.65 °C occurring over the course of a century in Victoria purely by random chance, as I explained here.

8) The statistical results presented here, and for New South Wales, imply that chaotic effects in the temperature record are important, and probably dominant in many cases, even over long (i.e. more than 100 years) timescales. 


vi) Addendum

One noticeable feature of the temperature trend in Fig. 19.3 is the large dip in temperature values before 1875. It may tempt some to think that this is evidence of an upward warming trend. It is not. It is because there are only two temperature records in Victoria with data before 1877, Melbourne Regional Office (Berkeley Earth ID: 151813) and Cape Otway Lighthouse (Berkeley Earth ID: 151786). 

The Cape Otway data exhibits no warming. So the mean temperature before 1880 is similar to that after 2000. However, the Melbourne data exhibits a strong warming trend of more than 1.5 °C from 1860 to 2010. This warming trend is cancelled after 1875 by the data from other stations that are generally stable or cooling. However, without these other stations, as is the case before 1875, the Melbourne data is able to dominate. The net result is that the overall trend suddenly jumps by almost 1 °C after 1875. For this reason the data before 1876 cannot be regarded as representative of the temperature of the entire state because it is dominated by one station: Melbourne Regional Office.

It should also be noted that changing the period for the MRT calculation can also affect the data slightly, either by changing the number of stations that qualify for the final averaging process, or by altering the offsets of the different datasets relative to each other. These effects are usually small but noticeable.


Fig. 19.8: Temperature trend for long and medium stations in Victoria since 1876. The best fit (red line) to the temperature data for 1880-2007 is -0.02 ± 0.07 °C per century.


For example, the trend in Fig. 19.8 above was derived by calculating the MRT for the period 1966-1995. This increases the number of stations incorporated into the trend by one to 66. The peak in the 5-year moving average at 1880 is now slightly higher than the one at 1890 so the overall trend (red line) becomes less negative, -0.02 ± 0.07 °C compared with -0.05 ± 0.08 for the data in Fig. 19.3 above. Note also that the data in Fig. 19.8 is truncated at year 1876. It is therefore much more representative of the overall trend in Victoria than the data shown in Fig. 19.3.


Monday, July 6, 2020

18. New South Wales - temperature trends PARABOLIC

In Post 7 and Post 8 I looked at the temperature trend in New Zealand since 1850. As I pointed out there, New Zealand has one of the longest and best temperature records in the Southern Hemisphere. However, in both respects the country is surpassed by Australia.

Overall, Australia has the best temperature records of any country in the Southern Hemisphere. Only Rio de Janeiro has a longer record than any of those found in Australia or New Zealand. And of the eight states that comprise Australia, the one with the most comprehensive records is New South Wales (NSW). Where New Zealand has 10 long station records with more than 1200 months of data, NSW has 33. It also has another 71 stations with more than 600 months of data, and another 31 with between 480 and 600 months of data. So, as the state with the best records, it is the obvious place to start when studying climate change in Australia.


Fig. 18.1: Location of NSW long stations (large squares) and medium stations (small diamonds). Those stations with a high warming trend since 1871 are marked in red.


i) The long station records

As already stated, these long stations have over 1200 months (or the equivalent of 100 years) of data. They are also fairly evenly distributed across NSW as shown in the map illustrated in Fig. 18.1 above. The stations in Fig. 18.1 are also differentiated according to the size of their warming trend. A high warming trend is defined as one where the trend is greater than twice the error or uncertainty in the trend (i.e. 95% confidence). Typically, the uncertainty for long stations is about ±0.1 °C per century, so the stations with a high warming trend will generally have a warming trend of over 0.2 °C per century. Only 11 of the 33 long stations fall into this category, while 14 have a negative trend (see Fig 18.2 below).


Fig. 18.2: Temperature trends of NSW weather stations for the period 1871-2010 plotted against the length of the temperature record in months.


The data in Fig. 18.2 shows that the stations with the largest warming trend are more likely to be those with the least data. This is mainly because they are also the stations that are least likely to have data that extends back before 1960. The long-term temperature trend in New South Wales is shown in Fig. 18.3 below and shows how the local climate has cooled for most of the 20th century before warming after 1960. As the shorter station records are concentrated in the post-1960 period, they tend to have warming trends, whereas the longer records that extend back to 1900 and beyond will be cooler because they also encompass the cooling period. The long station records will also be more important in determining the long-term trend of the region overall, again because they are the longest records and encompass the entire record, not just a small part of it.


Fig. 18.3: Temperature trend for NSW long stations since 1850. The best fit to the data has a gradient of +0.07 ± 0.08 °C per century.


The temperature trend in Fig. 18.3 was determined by calculating the mean of the anomalies of all 33 long stations. These stations are listed on Berkeley Earth here. The procedure for determining the temperature trend in Fig. 18.3 was as follows.

For each station record the monthly reference temperature (MRT) for each month was calculated by finding the mean temperature for that month for the period 1961-1990 (as explained here). These mean values were then subtracted from the raw temperature data to yield the anomaly for each month.  The mean deviation was then calculated for the anomaly and any data that was found to lie outside 6 deviations from the mean was labelled an outlier and excluded.

The factor of 6 was chosen because it relates to 6-sigma accuracy (99.9999998%), which is the standard tolerance level used in manufacturing and physics. As there could be up to 3000 data points per record potentially, an accuracy of less than 99.97% (3-sigma) would be highly likely to exclude a valid data point, even if it wasn't a genuine outlier. It would then require at least 4-sigma accuracy to differentiate an outlier and even then there would still be a 20% chance that the point was good.

Once the outliers have been excluded, the MRTs and the anomalies are recalculated. Finally, the mean of the anomalies of all 33 long stations is determined by adding the records and dividing the sum of the anomalies for each month by the number of temperature records for that month. This average trend is shown in Fig. 18.3.

The striking feature of the data in Fig. 18.3 is that there is no overall upward trend. The mean temperature in 2010 is no higher than it was in 1880, as indicated by the 5-year moving average. In between those dates the temperature trend declines by about 0.6 °C until the mid-1950s, and then rises again. The other main feature is the dip in the mean temperature before 1870. How long into the past this downward trend persists is impossible to determine though. The key question though is, what is the overall trend of the data? Are we seeing a rise or fall in temperature?

It may seem that the obvious way to answer this question is to perform a linear regression on all the available data. It is what Berkeley Earth do to their data, but this would be a mistake. The reason is that we do not have data that is randomly distributed around a straight line. There are oscillations in the data that we need to consider as well. The positions where these oscillations or peaks occur will affect the gradient of the best bit. That means our choice of time-frame for the fitting will affect our result as well.

As I pointed out in Post 4 (Fig. 4.7), the best fit to a sine wave is not a horizontal line of zero gradient, even if an integer number of periods are included in the fitting, and despite there always being equal amounts of data equally distributed above and below the x-axis. The key point is that the oscillatory component has to be symmetric about the centre of the fitting range, otherwise the asymmetry of the oscillations will bias the best fit line. For the data in Fig. 18.3 that means the fitting range needs to be from the first peak to the last peak, i.e. from 1884 to 2007. If we do this then we get a best fit trend of 0.07 ± 0.08 °C per century. In other words, there is a 19% probability that the trend is less than zero, and only a 5% probability it is more than +0.2 °C per century. Of course, if the data before 1884 is included, then the trend would be different. In fact it would be 0.23 ± 0.06 °C per century, but the data before 1884 is not a complete cycle.


Fig. 18.4: Temperature trend for NSW since 1840 according to Berkeley Earth.


Either way, the data in Fig. 18.3 bears no relation to that calculated by Berkeley Earth which is shown in Fig. 18.4 and is different is two major respects. Firstly, the Berkeley Earth trend is virtually zero from 1870 until 1960, and secondly it then exhibits a huge rise in temperature of more than 1 °C after 1960. The reason for this discrepancy will become apparent later in this post, but it is mainly to do with our dear old friend, the breakpoint adjustment.

One final point to note is the "noise level" of this averaged regional data. The anomaly data in Fig. 18.3 has a standard deviation of 1.03 °C even though it is an average of data from 33 different datasets, each of which also has a standard deviation of about 1 °C for its anomalies, as was illustrated in the last post. If those datasets were independent we would expect the "noise" or fluctuations in data values about the mean to reduce to about 0.17 °C, yet it doesn't. This shows that averaging data from different stations does not reduce the noise level significantly. This is because, as I pointed out in Post 11, the temperature data between stations is strongly correlated over distances up to at least 500 km, and therefore it is not independent in a statistical sense. It also means that even regional temperature data for entire countries or continents is still very noisy, and is likely to be subject to the same fractal behaviour I have described here and here. I will demonstrate this again in part (iii) below.


ii) The long and medium station records

The data in Fig. 18.3 only includes data from stations with more than 100 years of data. If we also include stations with over 40 years or 480 months of data (which I denote as medium length stations) the results do not change significantly from that illustrated in Fig. 18.3. In this case the MRTs were calculated for the period 1981-2000.


Fig. 18.5: Temperature trend for NSW long and medium stations since 1850. The best fit to the data has a gradient of +0.02 ± 0.08 °C per century.


The mean anomaly for all long and medium stations in New South Wales (and Australian Capital Territory) is shown in Fig. 18.5 above. The trend of the best fit line is +0.02 ± 0.08 °C per century for the data between 1884 and 2006. Nevertheless, the data is still very different from that shown in Fig. 18.6 from Berkeley Earth. In fact, if we use the Berkeley Earth adjusted data to construct an equivalent trend we get a very different result.


Fig. 18.6: Temperature anomaly and 5-year moving average for Berkeley Earth adjusted data from NSW since 1840. The anomaly data was constructed by averaging the adjusted anomalies for each Berkeley Earth dataset. The best fit line (in red) is for the period 1861-1960 and has a gradient of -0.09 ± 0.11 °C per century.


The data shown in Fig 18.6 above was constructed in exactly the same manner as that described above for the construction of the regional trends in Fig. 18.3 and Fig. 18.5. It was formed simply by averaging the data from all the relevant station datasets. In this case, however, the data was not the raw temperature anomalies from all long and medium stations, but the Berkeley Earth adjusted anomalies from all long and medium stations.

What we find is that simply by adding the Berkeley Earth adjusted anomalies with no additional weighting, we obtain curves that are almost identical to those published by Berkeley Earth and shown in Fig. 18.4. Moreover, the Berkeley Earth adjusted data in virtually horizontal from 1861 until 1960, and then it exhibits a huge rise in temperature of more than 1 °C up to about 2010. The gradient of the trend before 1960 is -0.09 ± 0.11 °C per century (red line in Fig. 18.6), while after 1960 it is +2.2 ± 0.2 °C per century (red line in Fig. 18.7 below).


Fig. 18.7: Smoothed temperature trends (12-month and 10-year) for NSW since 1840 based on Berkeley Earth adjusted data. The best fit line (in red) is for the period 1961-2010 and has a gradient of +2.2 ± 0.2 °C per century.


The data in Fig. 18.7 is just the regional monthly anomaly data in Fig. 18.6 that has been smoothed, either with a 12-month moving average, or a 10-year moving average. This data demonstrates two things. Firstly, because it is virtually identical to the data in Fig. 18.4, it shows that the data in Fig. 18.4 is also effectively just the sum of the adjusted anomalies. This then also demonstrates that the effect of any weighting that Berkeley Earth may have applied to those different stations, to account for differences in the density of stations across the region, is negligible in terms of the overall result, and can therefore be ignored. More importantly, it demonstrates that the differences between the averaged anomaly I have presented in Fig. 18.5 and the Berkeley Earth adjusted data in Fig. 18.6 cannot be due to a lack of appropriate weighting of the individual stations in Fig. 18.5. Therefore, the only place that the difference in the two datasets can come from is in the breakpoint adjustments (and other minor adjustments) which were introduced by Berkeley Earth. The sum total of these adjustments is shown below in Fig. 18.8 together with the best fit for the range 1881-2010.


 Fig. 18.8: The Berkeley Earth breakpoint adjustment for NSW since 1840 together with the difference between the Berkeley Earth adjusted anomaly and the raw anomaly. The best fit to the breakpoint adjustment is +0.35 ± 0.02 °C per century.


The effect of the breakpoint adjustments in Fig. 18.8 is two-fold. On the one hand they flatten the data before 1920. On the other, they increase the warming trend after 1940. The net result is that a climate record with large temperature fluctuations but no overall warming trend becomes a "hockey-stick" with a catastrophic warming of over 1 °C since 1960.


iii) Noise and scaling

In the last post I analysed the scaling of the noise for a single temperature record in New South Wales - Newcastle Nobbys Signal Station (Berkeley Earth ID - 152044). This station showed a scaling behaviour with a power law of -0.266. If we repeat that analysis, but for the averaged New South Wales monthly anomaly data in Fig. 18.5, we get the data shown in Fig. 18.9 below.


Fig. 18.9: Scaling of the noise for the New South Wales mean anomaly. The gradient of the best fit line is -0.272 ± 0.005 and R2 = 0.9985.


Here the standard deviation of the averaged data for NSW obeys a power law of the form N -a relative to the size of the smoothing average, N, where a = 0.272 ± 0.005. This is very similar to the values seen for individual temperature records, such as those of New Zealand that were discussed in Post 9 and Post 10, which implies that the averaging of multiple station records does not noticeably affect the overall scaling behaviour.In this case at least 33 station records are averaged. Normally we would expect such averaging to reduce the amplitude of the noise by at least a factor of 6. Yet here there is virtually no reduction in the noise level. This implies that the noise of each temperature record is not independent.

The consistency of this scaling behaviour also allows us to extrapolate in order to predict the value of the standard deviation of temperature records with much longer timeframes or moving averages. For example, from Fig. 18.9 we can infer that a 100-year moving average of the NSW temperature record would still have a standard deviation of 0.15 °C. That means that even over very long timescales there will be fluctuations of up to 0.6 °C in the mean temperature in NSW (to a 95% confidence level).


iv) Final thoughts

I pointed out earlier in this post that the trend I constructed in Fig. 18.5 would be largely dictated by data from the 33 long stations. It is worth noting that for most of these 33 records the temperature trend is very similar to the average shown in Fig. 18.5. Only one record closely resembles the Berkeley Earth trend featured in Fig. 18.4. That station is Sydney - Observatory Hill (Berkeley Earth ID - 151986), which just happens to be bang in the middle of the biggest city in the entire country.


v) Conclusions

1) The average temperatures in New South Wales (NSW) today are no greater than they were in the 1880s, 1920s and 1940s (see Fig. 18.5). This suggests that global warming trends were negligible during the 20th century, at least in NSW.

2) The NSW long-term temperature trend exhibits fluctuations of more than 0.5 °C over timescales of more than 100 years (see Fig. 18.5). So what climate scientists think is anthropogenic is, in reality, possibly (or probably?) just noise.

3) Breakpoint adjustments can completely change the form and shape of the long-term temperature trend (see Fig. 18.7). They are not neutral and they are probably not necessary, particularly if the data from multiple stations is going to be averaged anyway.

4) Breakpoint adjustments can add at least 0.35 °C per century to the long-term temperature trend for NSW (see Fig. 18.8). When combined with the changes to the shape of the trend, their effective contribution can be even greater.

5) The noise present in the NSW regional average data is no less than that seen in data from individual station records (i.e. both have a standard deviation of at least 1 °C) despite the regional average data being the result an averaging process of more than 33 records. This also suggests that the unadjusted monthly temperature fluctuations of most stations are highly correlated, otherwise the averaging process would reduce the noise level.

6) The noise in the NSW regional temperature average scales in a similar way to that seen in data for individual temperature records except that the power law is N -0.27, where N is the size of the sliding window in the moving average (see Fig. 18.9). The index of this power law is similar to the values seen in individual station records which appear to be centred around N -0.25.

7) As the standard deviation for the 60-month smoothed data is 0.35 °C, this means that there is a 50% probability of a temperature rise of more than 0.65 °C occurring over the course of a century in New South Wales purely by random chance, as I explained here. It also implies that chaotic effects are dominant, even over long (i.e. more than 100 years) timescales.


Addendum (21/03/2021)

The trend in Fig. 18.5 above was calculated by averaging the monthly anomalies from all stations in NSW with over 480 months of data. The anomalies were calculated relative to the MRT interval of 1981-2000, and for each station to qualify for inclusion in the average it needed to have at least 12 years of data in the 1981-2000 interval for each of the 12 months of the year.


Fig. 18.10: The number of station records included each month in the mean temperature trend for NSW in Fig. 18.5 when the MRT interval is 1981-2000.


The result is that almost 100 station records are included in the trend between 1970 and 1990 (see Fig. 18.10 above). Even between 1907 and 1957 there are over 50 station records included in the mean trend, and about 20 are included between 1880 and 1907. 


Fig. 18.11: Temperature trend for NSW since 1910 according to the Australian Government Bureau of Meteorology (BoM) in 2014.


In Fig. 18.4 I showed the temperature trend for NSW as reported by Berkeley Earth in 2014. It turns out this is very similar to the trend for NSW reported by the Australian Government's Bureau of Meteorology (BoM). The BoM version for 2014 is shown in Fig.18.11 above. It clearly shows that there is a temperature rise (in the 11-year moving average) of about 1.2 °C from 1950 to 2008, and a rise of about 0.7 °C from 1918 to 2008. Yet curiously the picture seven years later is a bit different, as is shown in Fig. 18.12 below.


Fig. 18.12: Temperature trend for NSW since 1910 according to the Australian Government Bureau of Meteorology (BoM) in 2021.


Note how many of the temperatures before 1970 have decreased compared to the equivalent data in Fig. 18.11, some by up to 0.2 °C, while many of those from 1980-2013 have increased, even though the reference period of 1961-1990 remains the same. This is clearly shown in the 11-year moving average where the net result is that the temperature rise from 1950 to 2008 has increased to about 1.35 °C, while the rise from 1918 to 2008 has increased to 0.9 °C. And yet the raw data for these periods haven't changed: only the interpretation and data analysis have.


Friday, July 3, 2020

17. Noise, fractals and scaling revisited

In Post 9 (Fooled by randomness) I presented evidence suggesting that the temperature records used to construct the global temperature trends might exhibit behaviour that could be fractal or quasi-fractal in nature. As a prelude to discussing the temperature trends in Australia, I thought I would first look at this quasi-fractal behaviour in more detail. To illustrate this phenomenon I am going to examine the data from the Newcastle Nobbys Signal Station in New South Wales (Berkeley Earth ID - 152044). I have chosen this station data because it is a fairly long temperature record (almost 150 years), and it is typical of the data seen in New South Wales.


Fig. 17.1: Temperature anomaly for Newcastle Nobbys Signal Station since 1860. Also shown are the standard deviation of the data (σ) and the predicted 95% (±2σ) and 99.7% (±3σ) confidence levels.


i) The noise spectrum

The temperature anomaly for the Newcastle station is shown in Fig. 17.1 above. The monthly reference temperature (MRT) for each month was calculated for the period 1961-1990, and these 12 values were subtracted from the raw data for the respective month to yield the anomalies shown in Fig. 17.1. The dataset has a standard deviation (σ) of 0.907 °C, which is indicated by the red lines on the graph. Also shown are the ±2σ (in green) and ±3σ boundaries (in orange).

Fig. 17.2: The predicted 68.27% σ), 95% (±2σ) and 99.7% (±3σ) confidence levels for data with a Gaussian probability density function and a standard deviation of σ.


If the data in Fig. 17.1 has a Gaussian frequency spectrum, you would expect to see a distribution of the data similar to that illustrated in Fig. 17.2 above, with 68.27% of data located within ±σ of the mean, 95.45% within ±2σ, and 99.73% within ±3σ. The data in Fig. 17.1 appears to be distributed roughly along these lines. In Fig. 17.3 below I have converted the anomaly data in Fig. 17.1 to a frequency distribution (with a certain amount of smoothing added in order to reduce the discrete data to a continuum) and then compared this distribution (in blue) to the expected Gaussian distribution with the same standard deviation (σ) of 0.907 °C (red curve). As can be readily seen, the degree of agreement is good. This suggests that this anomaly data, and probably most other anomaly data, does indeed have a probability distribution that is Gaussian.


Fig. 17.3: The calculated probability distribution of temperature 68.27% σ), 95% (±2σ) and 99.7% (±3σ) confidence levels for data with a Gaussian probability density function and a standard deviation of σ.


The real benefit of knowing the nature of the probability density function is that it allows us to calculate the likelihood that an extreme temperature change is the the result of a random process, or if not, then whether it may then be anthropogenic in origin. However, the data in Fig. 17.1 is not the temperature change. It represents the difference of each month's temperate from the mean, not the difference from a previous time. We can however, use the data for the former to simulate the latter. This is demonstrated in Fig. 17.4 below.


Fig. 17.4: Year on year change in the monthly temperature anomaly for Newcastle Nobbys Signal Station since 1860. Also shown are the ±σ, ±2σ and ±3σ confidence levels for the monthly anomalies in Fig. 17.1 for comparison.


The data in Fig. 17.4 was derived by calculating the temperature change between identical months one year apart using the anomaly data in Fig. 17.1. What is noticeable is that the spread of the data is greater in Fig. 17.4 than in Fig. 17.1 as indicated by the ±σ, ±2σ and ±3σ lines that refer back to the Fig. 17.1 data. In fact the standard deviation of the data in Fig. 17.4 should be a factor of √2 greater than that from which it is derived. This is because the error (or standard deviation) in the difference of two independent data readings, σ12, depends on the squares of the errors of the original two readings.

(17.1)

As the two readings being subtracted are from the same dataset, they will have the same standard deviation. Therefore, it follows that if σ1 = σ2 = σ, then σ12 = σ.√2 (so the standard deviation of the temperature difference is 41% larger than that of the original data). This means that extreme changes in temperature are more frequent than the data in Fig. 17.1 might suggest if one were to look only at the proportion of data that lies outside the ±σ, ±2σ or ±3σ boundaries.


ii) The scaling of the noise with data averaging or smoothing

A key point of note in Post 9 was the scaling behaviour of the noise. It has become apparent that some readers of this blog do not fully understand the methodology I used in Post 9, so I thought it might be useful to explain it again in a bit more detail here.

The central issue is how the data behaves as you smooth it. The smoothing process involves a moving average with a sliding window of data centred on the point that is being averaged. The aim is usually to reduce or eliminate the high frequency noise so that only the underlying trend remains. This is important in analysing climate data because the data in often very noisy, as is illustrated in Fig. 17.1. There is clearly an upward trend in that data between 1960 and 2010, but it is difficult to discern precisely what is happening before 1960. Smoothing can help identify this. However, smoothing also has some negative consequences. It inevitably removes any genuine structure in the data that has a similar frequency to the noise. It will also reduce the heights of maxima and raise the levels of minima in the data. The degree to which this happens will depend upon the sharpness of the turning points relative to the width of the sliding window.

The smoothing process is as follows. First you choose the number, N, of adjacent data points that you wish to average. The general rule is that the bigger the number N, the smaller in value the noise will become, and so the clearer the underlying trend will be.

Suppose you choose N = 5. That means for a given data value for the temperature in Fig. 17.1 (say for March 1966), you add the five temperature anomaly values centred on March 1966 and find the average or mean. That means adding the values for January, February, March, April and May anomalies together and dividing the result by five. Then you repeat this for every data point in Fig. 17.1 by moving along the dataset point by point. As you do so the set of five points to be averaged moves, hence the term "moving average". The width of the data being averaged (in this case N = 5) is the width of your "sliding window". The end result is a completely new dataset that follows the original data but has less noise. This is shown in Fig. 17.5 below where the 4 month smoothed data (N = 4) in green clearly has less noise than the original data in Fig. 17.1. However, smoothing the data by using 16 points (black curve in Fig. 17.5) reduces the noise level even further. What is interesting is why?


Fig. 17.5: The 4-month and 16-month smoothed monthly temperature anomalies for Newcastle Nobbys Signal Station.


The noise reduces because it is random, and if you add enough random numbers together eventually they will average to zero as the approximately equal number of negative and positive values you are adding will gradually cancel. If the noise is white noise, you would expect the mean amplitude of the noise, as represented by the standard deviation, σ, to decrease by a factor of √N. So, smoothing with a 4-month moving average (N = 4) should halve the noise amplitude or standard deviation, while smoothing with a 16-month moving average (N = 16) should reduce the standard deviation of the noise by a factor of 4. Except that does not happen with most temperature data.

Instead what we find is that a 4-month moving average (N = 4) only reduces the standard deviation of the noise by a factor of approximately √2, while a 16-month moving average (N = 16) only reduces it by a factor of about 2. In fact while the standard deviation, σ, for the anomaly data in Fig. 17.1 is 0.907 °C, we find that σ = 0.635 °C for N = 4, and σ = 0.429 °C for N = 16. So, rather than the noise decreasing by a factor of √N, the smoothing appears to reduce it much more slowly. How much more slowly is illustrated in Fig. 17.6 below. 


Fig. 17.6: The scaling behaviour of the smoothed temperature anomaly data for Newcastle Nobbys Signal Station. The graph shows the standard deviations (S.D.) for data smoothed with different moving averages (N). The gradient of the best fit line is -0.266 ± 0.006 and R2 = 0.9978.


The data in Fig. 17.6 shows the results for the standard deviation of the original data in Fig. 17.1 (N = 1), together with the standard deviation of same data after it has been smoothed with six different values for N (3, 6, 9, 12, 24, 60). The linear regression or best fit to the log-log plot of the data indicates that the smoothing reduces the standard deviation each time by a factor close to N 0.266 rather than the expected √N.

Because the trend line in Fig. 17.6 fits the data so well, it means we can use it to extrapolate with a high degree of confidence. That allows us to predict the standard deviation of the smoothed data for any level of smoothing, N, we might choose. For example, if N = 120, then each data point in the smoothed dataset would represent the mean temperature over a decade. Likewise, if N = 1200, each data point would represent the mean temperature for the century of data that was centred on that point in time.

Thus, the best fit line in Fig. 17.6 allows us to predict that σ = 0.252 °C for N = 120, and σ = 0.137 °C for N = 1200 for the smoothed temperature anomaly at this location. Given the rate of change in global temperatures that is claimed for global warming (i.e. 0.7-1.0 °C), these numbers are not insignificant and suggest that low frequency noise may be a significant component of any temperature rise climate scientists claim they are detecting.


iii) The implications for 100-year temperature trends

To illustrate the potential implications of noise in the temperature record, consider the following example. The data in Fig. 17.1 has a standard deviation of 0.907 °C. When smoothed with a 5-year moving average this reduces to 0.31 °C. That implies that 95.45% of the data will be within ±0.62 °C of the mean and 2.275 % will have values that are more than 0.62 °C above the mean. The final 2.275% will have values that are more than 0.62 °C below the mean.

But as we saw in Fig. 17.4, when we look at changes in temperature between years, the standard deviation increases by about a factor of √2. For the data in Fig. 17.4 that means a value of 0.43 °C, and now the fraction of data that sees a rise of 0.86 °C will be p = 2.275%.

But what we really want to know is how likely any temperature rise of this magnitude will be over a 100 year period if it occurs purely by chance. The answer to that will (approximately) be that the overall probability P100 will be determined by

P100 = 1 - (1 - p)20 
(17.2)

As p = 0.02275, then P100 = 0.37. The power of 20 in Eq. 17.2 reflects the fact that in a 100 year interval there will be an average of 20 possible attempts for the 5-year average to jump by the desired amount or more. In other words, there is a 37% probability of a 0.86°C temperature rise occurring purely by random chance. That is not insignificant. To find the probability of other temperature rises occurring, the maths is more difficult, but not impossible. We just need to find p.

We now know that the anomaly fluctuations obey a Gaussian probability distribution of the form

(17.3)

where σ is the standard deviation and ∆T is the change in temperature from the mean. The probability p that ∆T exceeds some critical value ∆T0 will be given by

(17.4)

where x = ∆T0/σ√2 and erfc(x) is the complementary error function. Using these equations we can now find the probability of other temperature rises occurring naturally via random processes.

As I have already demonstrated, there is a 37% probability of a 0.86°C temperature rise in 100 years due to random chance. In other words, if ∆T0 = 2σ, and σ = 0.43 °C, then p = 0.02275 and P100 = 0.37. Similarly, the above analysis means that this probability (P100) will increase to 89% for a ∆T0 = 0.7 °C temperature rise and fall to 18% for a 1.0 °C rise for the same value of σ. In addition, the data implies that there will be a 50% probability of a random temperature rise of more than 0.78 °C at some time over the century. It should also be remembered that all these probabilities are based on the initial standard deviation of 0.907 °C. If the standard deviation increases (as is seen, for example, in other datasets), then so too will the probabilities.


iv) The scaling of the noise frequency

So far I have only considered the scaling behaviour of the anomaly amplitude. But it is clear from the data in Fig. 17.1 and Fig. 17.5 that smoothing the data changes the underlying frequency of the fluctuations as well. One might expect this frequency to decrease linearly with the smoothing factor N, but it does not.

The easiest way to quantify the frequency of the fluctuations is to count the number of times the data crosses the mean value of the anomaly in a given time interval. For example, in Fig. 17.1 the data crosses the mean value 317 times over the course of 140 years. This decreases to 155 for a 3-month moving average, and 54 for a 12-month moving average.


Fig. 17.7: The scaling behaviour of the mean period of the smoothed temperature anomalies for Newcastle Nobbys Signal Station for different moving averages (N). The gradient of the best fit line is 0.756 ± 0.031 and R2 = 0.9917.


Plotting this data on a log-log plot again yields a linear trend indicating that the period of the fluctuations increases as N a. In this case, though, a = 0.756 ± 0.031 with a residual that is 9% of the standard deviation of y-values(see Fig. 17.7 above).

In Post 9 I showed theoretical plots (see Figs. 9.7 - 9.10) to highlight how the scaling could be used to predict the qualitative behaviour of longer time series. However, these plots did not include the appropriate scaling of the time axis. It assumed the scaling of the time base was proportional to N. If the correct scaling is now included, the results will be similar, but the time axis will expand slightly.


Fig. 17.8: Simulated 2000 year temperature anomalies with 50-year mean for Newcastle Nobbys Signal Station.


As an example of the power of predictive scaling, consider the scaled data shown in Fig. 17.8 above. This data aims to simulate the behaviour of the Newcastle Nobbys Signal Station (Berkeley Earth ID - 152044) time series over an arbitrary 2000 year time period where the data will typically have been smoothed to a resolution of 50 years. That means N = 600 and the standard deviation of the fluctuations will be 0.183 °C. The time base and the mean period of the fluctuations, however, will increase by a factor of about 120. Finally the data is filtered so that only every 6th point is plotted. This corresponds to one point per decade. What Fig. 17.8 shows is that large swings in the mean decadal temperature of more up to 0.5 °C within a century are expected to be fairly common. The big question is, is it realistic? And can we find any corroboration for it?


Fig. 17.9: A 2000 year proxy temperature record for China.


Of course we do not have temperature records that are 2000 years long, but we do have some proxy records, including this one from China (see Fig. 17.9 above). Intriguingly, the China data in Fig. 17.9 shows many features that are not that dissimilar to the simulated data in Fig. 17.8. The standard deviations of the fluctuations in both appear to be around to 0.2 °C and the period of the fluctuations appear similar as well. So, is the China data evidence of the validity of our approach? Quite possibly, but then I might be biased.


v) Conclusions

Wherever I look in climate science data, all I can see is noise. It appears that much of this noise is more persistent than that seen with typical white noise, and this becomes significant in temperature trends that are several decades or centuries in length. It leads to long timescale (low frequency) fluctuations that are comparable in amplitude to those currently being attributed to global warming. This represents a serious challenge to current climate science orthodoxy, because I cannot see how you can definitively distinguish one effect from the other, based on the available data.

In physics we normally aim for a 3-sigma level of confidence before we even begin to make claims of proof regarding any theory or hypothesis. Normally it requires 5-sigma levels of confidence. The Higgs boson was confirmed with a 5-sigma level of confidence that has now risen to nearly 7-sigma. Yet most climate data seems incapable of exhibiting even a 1-sigma level of confidence when compared to any available theory or model. But the claims made by many climate scientists about said data would seem to imply otherwise. None of their pronouncements ever seem to be qualified. It is this lack of doubt and critical thinking among climate scientists that I find most troubling.


Fig. 17.10: A 10,000 year proxy temperature record for Greenland based on the GISP2 ice core isotope data.


Take the data in Fig. 17.10  above, for example. This is a plot of the inland temperature of the Greenland ice sheet over the last 10,000 years based on ice core data. It shows large fluctuations in temperature that are comparable to those seen in modern temperature records, but the mean period of the fluctuations is much larger. That is probably because the timescale is much larger. But the question is: are these fluctuations real in the sense that there is an immediate identifiable cause for them? Or are they just noise? The fact is we don't know. Climate scientists have proposed countless theories to account for the fluctuations, but none are watertight. Yet the possibility that it might all be just noise resulting from the afterglow of a much bigger physical event (such as Milankovitch oscillations in this case), in the same way that the cosmic microwave background is the afterglow of the Big Bang, still doesn't appear to register with most of them.